ai · tech — OCT 22, 2026
Which Model Wrote That Line?
A signal that doesn't exist yet.
People in tech spend a lot of time thinking about token cost and speed. We almost never think about which model wrote which line.
Wondering out loud about this: pre-AI, a codebase gets more mature over time, and the % of lines getting rewritten goes down. Now, AI churns code constantly, so you can't tell good churn from wasted churn without attribution.
Frequent heavy rewrites suggest time is being wasted. git commits tell part of that story, but being able to tie a line of code back to the model that wrote it gives us another signal entirely.
I realised Cursor and Claude already have this data, but the developers using these tools most likely don't. The data exists, it's just not pointed at us.
So I built a small tool (in Rust, of course) that records which model wrote which characters, under which prompt, in which session.
Replay it and you get the actual composition of a codebase; what fraction of each file came from each model, and how much of it is still there today.
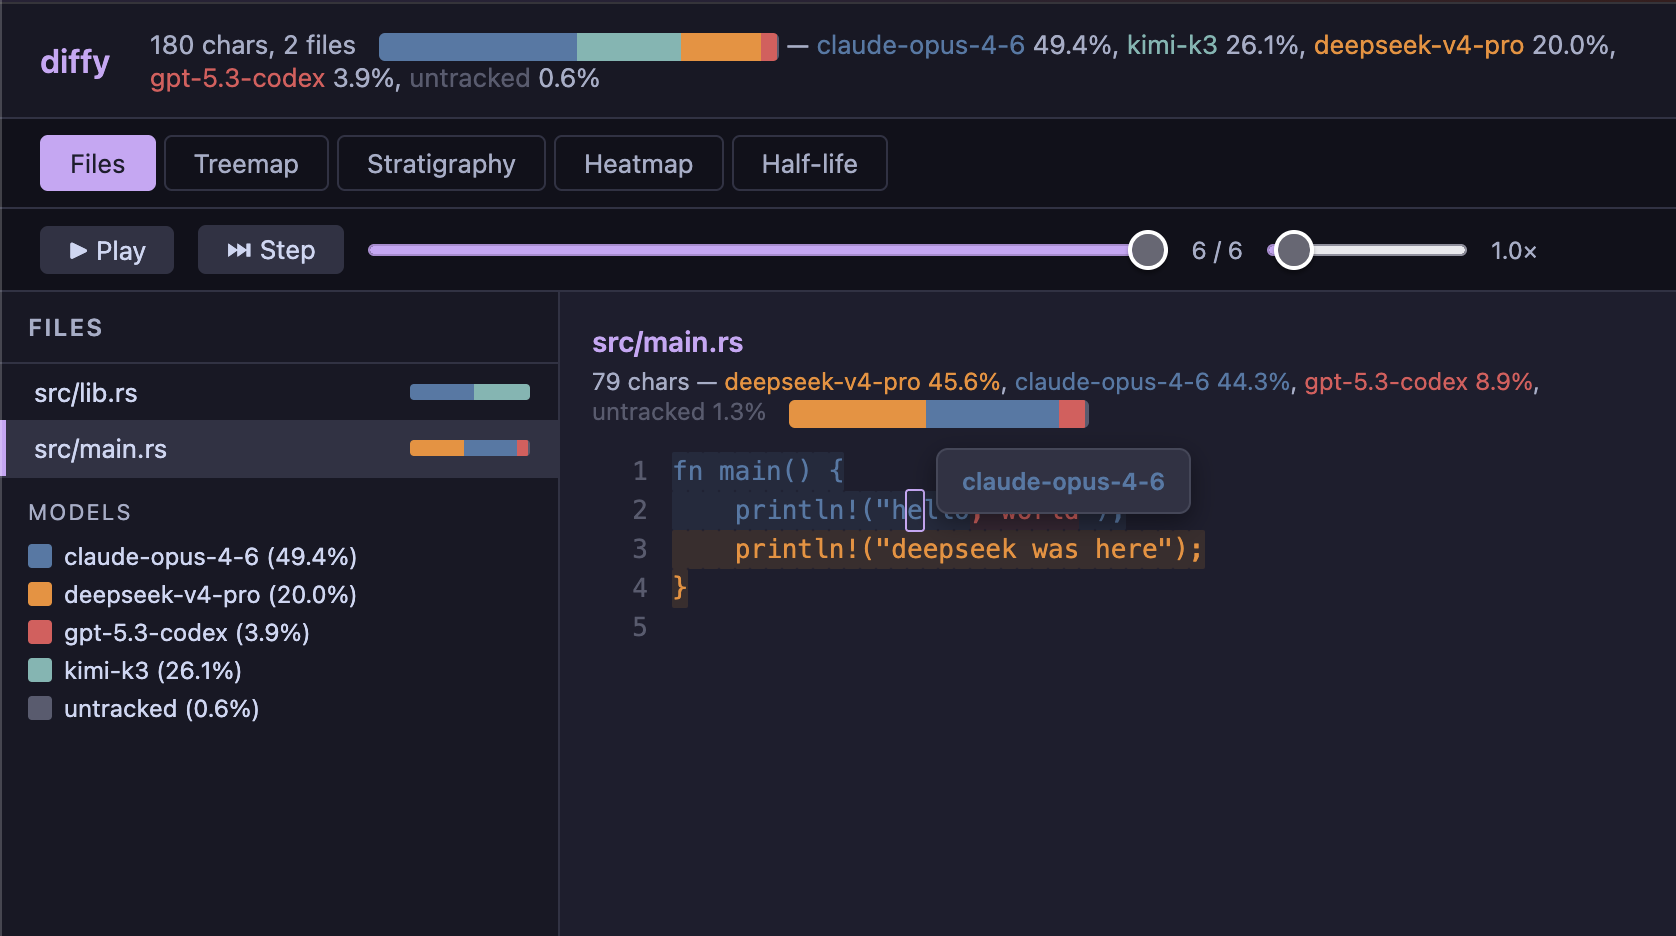
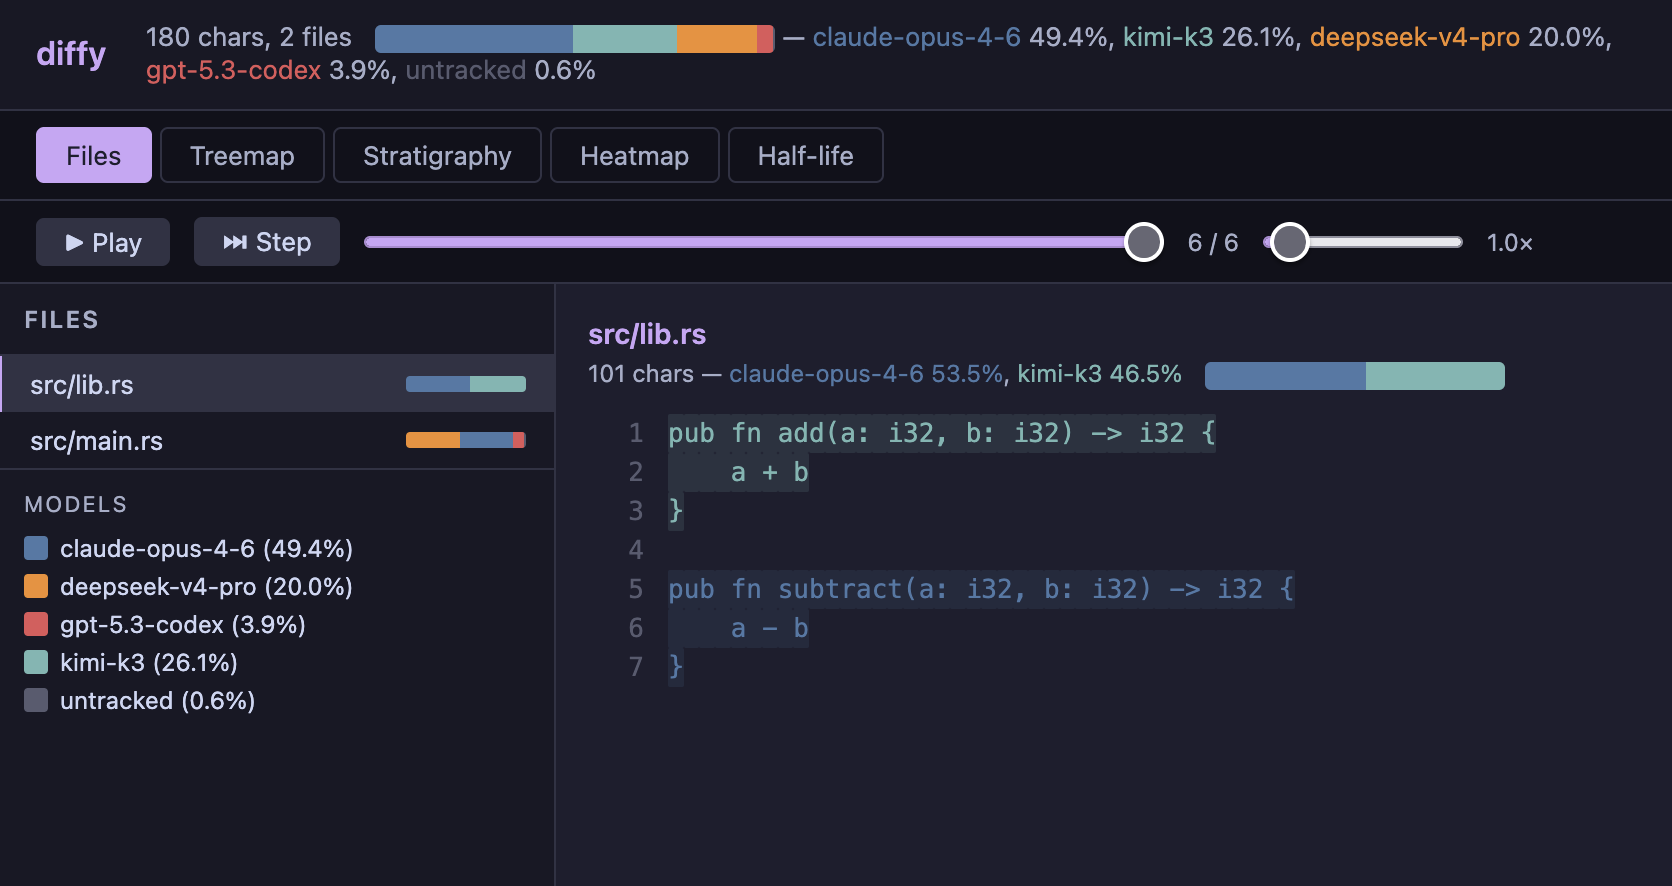
I'm not going to claim the data proves anything yet. I don't want to make claims about how useful it is.
But what it adds is a signal that doesn't exist otherwise: which model wrote which line.
On its own that's just data, but providing extra data on which model wrote which line can reveal patterns at scale, when enough of it has been collected.
I'd rather have the signal and let the patterns emerge, than assert a conclusion I can't back yet.